
Your application probably checks the data people type in. The email field must not be empty, the age must be a positive number, the username must not already be taken. That’s good. But what happens when someone imports a spreadsheet directly, a second app writes to the same table, or a developer runs a quick fix by hand? Application checks don’t help then.
Constraints are rules you put on the table itself. The database checks them on every insert and update, no matter where the data comes from. They’re your last line of defence for clean data, and they cost almost nothing to add.
Quick answer: what are constraints in SQL?
Constraints are rules on a table’s columns that the database enforces on every insert and update. There are six main types: NOT NULL (a value is required), UNIQUE (no duplicates), PRIMARY KEY (identifies each row), FOREIGN KEY (the value must exist in another table), CHECK (a condition must be true) and DEFAULT (a value is filled in automatically).
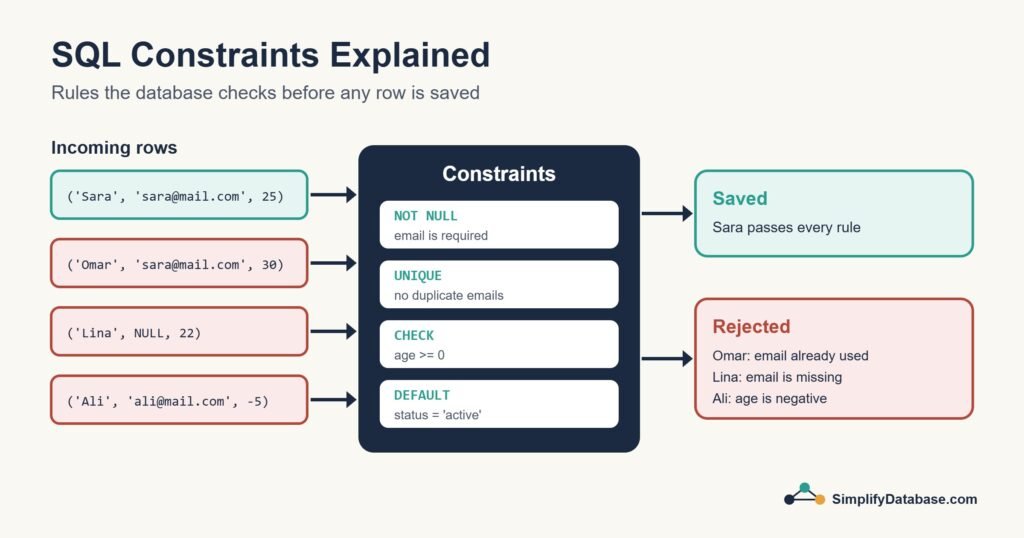
Table of Contents
The Main Types of Constraint
| Constraint | What it guarantees | Example |
|---|---|---|
NOT NULL | The column always has a value | Every customer must have an email |
UNIQUE | No two rows share the same value | Two customers can’t use the same email |
CHECK | A value meets a condition you define | Age must be 0 or more |
DEFAULT | A value is filled in when none is given | New accounts start as ‘active’ |
PRIMARY KEY | Unique and not null, identifies each row | customer_id |
FOREIGN KEY | A value must exist in another table | An order’s customer_id must be a real customer |
Primary and foreign keys have their own article (Primary Keys vs. Foreign Keys), so here I’ll focus on the other four.
A Table With Constraints
CREATE TABLE customers (
    customer_id INT PRIMARY KEY,
    name        VARCHAR(100) NOT NULL,
    email       VARCHAR(150) NOT NULL UNIQUE,
    age         INT CHECK (age >= 0 AND age <= 120),
    status      VARCHAR(10) NOT NULL DEFAULT 'active',
    created_at  DATE NOT NULL DEFAULT CURRENT_DATE
);
This works as written in PostgreSQL. In MySQL (8.0.13 and later) wrap the default in brackets: DEFAULT (CURRENT_DATE). In SQL Server use DEFAULT CAST(GETDATE() AS DATE).
Every rule about this table is now written right next to the column it protects. Let’s look at each one.
NOT NULL: This Value Is Required
By default, columns accept NULL (no value). NOT NULL turns that off:
INSERT INTO customers (customer_id, name, email)
VALUES (1, 'Lina', NULL);
-- Error: column "email" cannot be NULL
My advice: make columns NOT NULL unless you have a real reason to allow missing values. Fewer nulls means fewer surprises in your queries. (Nulls behave strangely, which I explain in NULL in SQL Explained.)
UNIQUE: No Duplicates Allowed
UNIQUE stops two rows from having the same value in a column:
INSERT INTO customers (customer_id, name, email) VALUES (1, 'Sara', 'sara@mail.com');
INSERT INTO customers (customer_id, name, email) VALUES (2, 'Omar', 'sara@mail.com');
-- Error: duplicate value violates unique constraint
UNIQUE vs. PRIMARY KEY
| PRIMARY KEY | UNIQUE | |
|---|---|---|
| How many per table | One | As many as you need |
| Allows NULL? | Never | Yes (how many nulls depends on the database) |
| Purpose | Identify the row | Prevent duplicate business values like emails or codes |
On nulls: PostgreSQL and MySQL allow many NULL values in a unique column, while SQL Server allows only one. If you need “unique when filled in” in SQL Server, use a filtered unique index.
Unique across several columns
Sometimes the combination must be unique, not each column on its own. A student can enrol in many courses, but not the same course twice:
CREATE TABLE enrollments (
    student_id INT NOT NULL,
    course_id  INT NOT NULL,
    CONSTRAINT uq_student_course UNIQUE (student_id, course_id)
);
Behind the scenes, a unique constraint is enforced with an index, so it also speeds up searches on those columns.
NOT NULL and UNIQUE together
UNIQUE on its own still lets rows leave the column empty. When a value must be both filled in and different for every row, like a username or an employee code, combine the two:
CREATE TABLE employees (
    employee_id   INT PRIMARY KEY,
    employee_code VARCHAR(20) NOT NULL UNIQUE,
    national_id   VARCHAR(20) UNIQUE          -- optional, but no duplicates
);
NOT NULL UNIQUE behaves almost like a second primary key. It’s the usual choice for a “natural” business code when the table already uses a numeric ID as its primary key.
CHECK: Your Own Business Rules
CHECK lets you write any condition that must be true for every row:
ALTER TABLE products
ADD CONSTRAINT chk_price_positive CHECK (price > 0);

ALTER TABLE products
ADD CONSTRAINT chk_discount_range CHECK (discount BETWEEN 0 AND 50);

ALTER TABLE bookings
ADD CONSTRAINT chk_dates CHECK (check_out > check_in);
The last one compares two columns in the same row, which is perfect for date ranges. One thing to remember: a CHECK passes when the result is unknown, so CHECK (age >= 0) still accepts NULL. Add NOT NULL if the value is required.
Also note that MySQL only started enforcing CHECK constraints in version 8.0.16. Older versions accepted the syntax and silently ignored it.
DEFAULT: Sensible Starting Values
DEFAULT fills in a value when an insert doesn’t provide one:
INSERT INTO customers (customer_id, name, email)
VALUES (3, 'Huda', 'huda@mail.com');

-- status is 'active' and created_at is today's date, automatically
Defaults are great for status flags, creation dates and counters that start at zero. Strictly speaking, DEFAULT isn’t a rule that rejects data, but it’s defined in the same place and it keeps inserts short and consistent.
Name Your Constraints
If you don’t name a constraint, the database invents a name like CK__customers__age__3B75D760. That’s painful when it shows up in an error message or when you need to drop it. Give each one a clear name:
CREATE TABLE customers (
    customer_id INT,
    email       VARCHAR(150) NOT NULL,
    age         INT,
    CONSTRAINT pk_customers       PRIMARY KEY (customer_id),
    CONSTRAINT uq_customers_email UNIQUE (email),
    CONSTRAINT chk_customers_age  CHECK (age >= 0)
);

-- Removing one later
ALTER TABLE customers DROP CONSTRAINT chk_customers_age;
Adding Constraints to an Existing Table
You can add constraints later with ALTER TABLE, but the existing data has to pass the rule first. If there are already duplicate emails, adding UNIQUE fails. Find the problem rows before you try:
-- Which emails are duplicated?
SELECT email, COUNT(*)
FROM customers
GROUP BY email
HAVING COUNT(*) > 1;
Fix or merge those rows, then add the constraint.
Constraints in a Real Business Database
The examples above use a small customers table. Here is how the same rules protect an accounting or ERP database, where bad data costs real money.
Journal lines: one side only
In a general ledger every line is either a debit or a credit, never both and never neither:
ALTER TABLE gl_journal_lines
ADD CONSTRAINT chk_gl_lines_one_side
CHECK ( (debit > 0 AND credit = 0) OR (credit > 0 AND debit = 0) );
Without this rule, a bad import line with both values filled in still saves, and the trial balance stops balancing. Someone then spends a day finding the cause.
Invoice numbers: unique per branch and year
Invoice numbers often restart each year and differ between branches, so the number alone isn’t unique, but the combination is:
ALTER TABLE invoices
ADD CONSTRAINT uq_invoices_branch_year_no
UNIQUE (branch_id, fiscal_year, invoice_no);
“Unique when filled in” in SQL Server
A tax registration number may be optional, but two customers must never share one. A UNIQUE constraint in SQL Server allows only one NULL, so use a filtered unique index instead:
CREATE UNIQUE INDEX uq_customers_tax_no
ON customers (tax_no)
WHERE tax_no IS NOT NULL;
The NOCHECK trap
During a big data migration, people often switch constraints off to speed up loading and then switch them back on:
ALTER TABLE invoices NOCHECK CONSTRAINT ALL;
-- ... bulk load ...
ALTER TABLE invoices CHECK CONSTRAINT ALL;   -- looks fine, but isn't
The second line protects new rows only. SQL Server doesn’t re-check the rows already in the table, so it marks those constraints as not trusted. Bad rows from the load stay in place, and the query optimizer stops using those constraints to simplify plans. Re-enable them with the double CHECK, which validates every row:
ALTER TABLE invoices WITH CHECK CHECK CONSTRAINT ALL;And find any that are still untrusted:
SELECT OBJECT_NAME(parent_object_id) AS table_name, name, type_desc
FROM sys.check_constraints WHERE is_not_trusted = 1
UNION ALL
SELECT OBJECT_NAME(parent_object_id), name, type_desc
FROM sys.foreign_keys WHERE is_not_trusted = 1;
Turning constraint errors into friendly messages
Clear constraint names pay off in the application. In a Delphi or Laravel app you can catch the database error, look for the constraint name in the message, and show something the user understands:
| Constraint name in the error | Message to the user |
|---|---|
uq_invoices_branch_year_no | “This invoice number already exists for this branch and year.” |
chk_gl_lines_one_side | “Enter either a debit or a credit on each line, not both.” |
That’s only practical when the constraint is called uq_invoices_branch_year_no and not UQ__invoices__3213E83F.
How to List the Constraints on a Table
When you inherit a database, the first question is often “what rules does this table already have?” Each database has its own way to show them.
SQL Server
EXEC sp_helpconstraint 'dbo.customers';

-- or as a query
SELECT name, type_desc
FROM sys.objects
WHERE parent_object_id = OBJECT_ID('dbo.customers')
  AND type IN ('PK', 'UQ', 'F', 'C', 'D');
MySQL
SELECT constraint_name, constraint_type
FROM information_schema.table_constraints
WHERE table_schema = DATABASE()
  AND table_name = 'customers';
PostgreSQL
SELECT conname, pg_get_constraintdef(oid) AS definition
FROM pg_constraint
WHERE conrelid = 'customers'::regclass;
NOT NULL usually doesn’t appear in these lists, because most databases store it as a property of the column. Check is_nullable in information_schema.columns instead. For more syntax differences between the three databases, see the SQL Server vs MySQL vs PostgreSQL cheat sheet.
Common Constraint Errors and How to Fix Them
Constraint errors look scary, but the message almost always tells you which rule was broken. Here are the ones you’ll meet most often:
| Error message (shortened) | Database | What it means |
|---|---|---|
| Violation of UNIQUE KEY constraint … Cannot insert duplicate key | SQL Server (Msg 2627) | The value already exists in a UNIQUE or primary key column |
| Duplicate entry ‘…’ for key ‘…’ | MySQL (1062) | Same as above |
| duplicate key value violates unique constraint | PostgreSQL (23505) | Same as above |
| The INSERT statement conflicted with the CHECK constraint | SQL Server (Msg 547) | A CHECK rule returned false. The same message number is used for foreign key conflicts |
| Check constraint ‘…’ is violated | MySQL (3819) | A CHECK rule returned false |
| new row … violates check constraint | PostgreSQL (23514) | A CHECK rule returned false |
| there is no unique constraint matching given keys for referenced table | PostgreSQL (42830) | A foreign key points at columns that aren’t a primary key or UNIQUE |
For duplicate and check errors, look at the row you were saving, not the table: the constraint name in the message tells you which column broke the rule. If the duplicates are already in the table, my guide to finding and deleting duplicate rows shows how to clean them up.
Fixing “there is no unique constraint matching given keys”
PostgreSQL raises this when you create a foreign key that points at a column (or set of columns) with no primary key or unique constraint. A foreign key must reference something guaranteed to be unique:
CREATE TABLE branches (
    branch_code VARCHAR(10) NOT NULL   -- no PRIMARY KEY or UNIQUE
);

CREATE TABLE invoices (
    invoice_id  INT PRIMARY KEY,
    branch_code VARCHAR(10) REFERENCES branches (branch_code)
);
-- ERROR: there is no unique constraint matching given keys
--        for referenced table "branches"

-- Fix: make the referenced column unique first
ALTER TABLE branches
ADD CONSTRAINT uq_branches_code UNIQUE (branch_code);
With a multi-column key, the foreign key must list exactly the same columns as the unique constraint. SQL Server and MySQL have the same rule, they just word the error differently. See Primary Keys vs. Foreign Keys for how the two work together.
Constraints vs. Application Checks
People sometimes ask whether they need both. I always say yes:
- Application checks give users friendly messages straight away (“Please enter a valid email”).
- Database constraints guarantee the rule holds for every single row, from every source, forever.
Years of working with business systems have taught me that any rule only enforced in the application will be broken eventually by an import, a script or a second app.
Frequently Asked Questions
What are the types of constraints in SQL?
The six main ones are NOT NULL, UNIQUE, PRIMARY KEY, FOREIGN KEY, CHECK and DEFAULT. Some databases add others, such as PostgreSQL’s EXCLUDE constraint, but these six are the ones you’ll use every day.
What’s the difference between a column-level and a table-level constraint?
A column-level constraint is written next to one column (email VARCHAR(150) UNIQUE). A table-level constraint is written separately and can cover several columns (CONSTRAINT uq_student_course UNIQUE (student_id, course_id)). They do the same job. Use the table-level form when the rule involves more than one column or when you want to give it a clear name.
Do constraints slow down inserts?
Very slightly, because the database has to check each rule. UNIQUE and primary keys also maintain an index. For normal applications the cost is tiny compared with the cost of cleaning bad data later, and trusted constraints can even help the optimizer build faster query plans.
Can I turn a constraint off temporarily?
Yes. In SQL Server use NOCHECK CONSTRAINT, but read the NOCHECK trap above before you do: switch it back on WITH CHECK or the database stops trusting it. In MySQL you can set FOREIGN_KEY_CHECKS = 0 for foreign keys during a load. In most cases it’s safer to fix the data than to switch a rule off.
Conclusion
Constraints are rules the database enforces for you: NOT NULL for required values, UNIQUE for no duplicates, CHECK for your own conditions and DEFAULT for sensible starting values. Add them when you create a table, give them clear names, and you’ll spend much less time cleaning up bad data later.
If you’re designing a new database, pair this with our guides to data types and normalization.
Related articles
- SQL Triggers Explained Simply: run code automatically when data changes.
- SQL INSERT, UPDATE and DELETE: add, change and remove rows safely.
- Primary Keys vs. Foreign Keys: the two key constraints, explained with examples.
- How to Find and Delete Duplicate Rows: clean up the data before you add a UNIQUE constraint.